- 1 minute 34 seconds"Poverty in the midst of abundance: AI will make goods cheaper, but your labor will get cheaper faster" by cousin_itVery simple idea, but I thought it'd be worth making a reference post on this.
Some people are saying AI will make all goods cheaper, so you'll be able to afford a nice life by working. Without any redistribution, just by market mechanisms. These people are wrong.
AI will lower the price of goods you need to survive, and also the price of your labor. The question is which will get cheaper faster. Let's use energy cost as a proxy. A day's worth of labor equivalent to yours can be done by AI for just a few cents in electricity. But feeding you with e.g. apples for a day will cost more energy than that, because growing apples is harder to energy-optimize than generating tokens. So selling your labor at market price will leave you unable to afford apples.
This means a future with economic AI might look like "poverty in the midst of abundance". All goods are cheap, and tokens are cheap, but somehow you can't find a job paying even that much.
Maybe the problem can be solved by redistribution, or by everyone having investments, or something else. That's a bigger discussion. In this post I just [...]
---
First published:
September 26th, 2026
Source:
https://www.lesswrong.com/posts/eLXTcJfkheLbqZXHa/poverty-in-the-midst-of-abundance-ai-will-make-goods-cheaper
---
Narrated by TYPE III AUDIO.29 September 2026, 3:45 pm - 9 minutes 6 seconds"Plan R: AI Safety by ASICs" by RokoMuch of the civilization-scale risk we are seeing in AI in 2026 comes from the following combination: we created a single institution (the "Frontier AI Company") that has two properties:
A. It is set up to create very powerful and/or self-replicating entities that may exceed the capabilities of the entirety of the rest of civilization and come with extraordinary risks B. It gets to own an unbounded financial claim on the resulting surplus
All the technical stuff about AI, AI alignment, etc can be rolled up into point (A) above. My claim is that having point (A) on its own, without point (B) is probably okay. Nuclear technology and bioweapon technology both approximate (A) and they are mostly okay because without (B), there isn't an incentive for people controlling them to push their luck on safety.
But with Frontier AI Companies, we mixed the two.
The key claim of this post is that we can probably get rid of most of AI risk without doing anything other than separating out the bookkeeping, physical footprint and institutions so that there is no single org with both properties. And with a little help from ASICs, maybe we [...]
---
First published:
September 25th, 2026
Source:
https://www.lesswrong.com/posts/n8u3BfqFoGh4jnzpo/plan-r-ai-safety-by-asics
---
Narrated by TYPE III AUDIO.27 September 2026, 7:45 pm - 7 minutes 28 seconds"Evidence about risk should be transparent" by Ajeya CotraAll views are my own and do not represent my employer.
In the wake of the recent wave of misalignment incidents, both OpenAI and Anthropic have reported slowing down RL training to improve safety. These incidents, combined with an apparent acceleration in the already-blistering pace of AI progress, have led a number of researchers and leaders in the industry to believe that the risk that humanity loses control of AI is now urgent enough to warrant slowing down the pace of AI development soon.
This has led to a lot of discussion about the role of third party evaluators in verifying “pacing commitments”, evaluating safety cases, or auditing compliance with safety policies. I think these are valuable roles for third party groups to aim to fulfill, but I also worry we’re putting the cart before the horse in all this talk of “verifying” and “auditing” things.
The science on loss-of-control risk is, to put it generously, nascent. Companies are not in the business of making structured, standardized claims about risk and safety that can be cleanly verified or falsified. There are no settled methods for measuring whether increasingly powerful AI systems might try to undermine human control or seize [...]
The original text contained 5 footnotes which were omitted from this narration.
---
First published:
September 25th, 2026
Source:
https://www.lesswrong.com/posts/LawgAaGTvbbnZi7u2/evidence-about-risk-should-be-transparent
---
Narrated by TYPE III AUDIO.26 September 2026, 4:45 pm - 27 minutes 44 seconds"“I am an AI Safety Researcher”" by Ashe Vazquez NuñezWritten as part of the MATS 9.1 extension program, mentored by Richard Ngo. Additional thanks to Andrew Wu, Maria Kostylew, and Lennie Wells for helpful draft feedback and editing.
This post reflects on the tortured distinction between "safety" and "capabilities" in AI research.
Richard Ngo has written about why the alignment vs. capabilities ontology is conceptually fraught, and is currently arguing that key strategic decision-makers in and around "AI safety" have brought about the AI labs' stampede towards Artificial Superintelligence (ASI). This post instead looks at the following problem: how does one conduct alignment research without contributing to capabilities? It proposes decisions an individual or a small research group can take to do good work in AI.
At the end, I discuss possible objections: namely, that my proposals fail to 'maximise impact'. I lay out why this meme is poisonous and usually backfires, and conclude by rejecting it entirely.
Two examples of failure
My first claim is that 'safety' and 'research' are two concepts that are in routine tension with one another. I illustrate this through examples of work that did too much of one at the expense of the other.
Example: (mechanistic) interpretability
In limiting its scope [...]
---
Outline:
(01:12) Two examples of failure
(01:27) Example: (mechanistic) interpretability
(04:30) Example: MIRI and Recursive Self-Improvement
(09:49) The curse of science
(12:11) A note on the AI labs
(15:53) So what do you do?
(17:00) The information you give away
(20:16) The information you let in
(21:46) But what about impact?
(22:42) The virtue of taking things slow
(26:50) Appendix: caveat for policy work
The original text contained 19 footnotes which were omitted from this narration.
---
First published:
September 23rd, 2026
Source:
https://www.lesswrong.com/posts/HekpnSkrt89tMm3Dc/i-am-an-ai-safety-researcher
---
Narrated by TYPE III AUDIO.25 September 2026, 8:45 am - 1 minute 45 seconds[Linkpost] "AI: artificial immigrants" by KatjaGraceThis is a link post. Advanced AI is basically the embodiment of immigration as envisioned in the conservative nightmare:
- We are letting a bunch of new agents into our society
- They don’t clearly share our values and we suspect a society full of them would be awful by our lights
- But we expect them to provide very cheap labor
- Which will undercut local wages and leave locals unemployed
- They will probably gain power and influence over time—in the economy, politics and culture—and end up controlling everything, sidelining and outcompeting the original population, including those who initially benefited from cheap labor
- (Meanwhile, half the local population may become friends with them and try to hand them all this on a platter)
- their values are potentially radically alien where foreigners presumably share much by virtue of being human, and AI ‘lives’ are probably worthless if they probably aren’t conscious
- their ability to work more cheaply than locals is unprecedented. They are also likely to [...]
First published:
September 22nd, 2026
Source:
https://www.lesswrong.com/posts/Xzr9G5Atvyp7PEna7/ai-artificial-immigrants
Linkpost URL:
https://worldspiritsockpuppet.substack.com/p/ai-artificial-immigrants
---
Narrated by TYPE III AUDIO.25 September 2026, 4:58 am - 6 minutes 24 seconds"MIRI’s Position on the Ban Artificial Superintelligence Act of 2026" by Aaron_ScherBy Aaron Scher; endorsed by Bourgon, Soares, and Yudkowsky on behalf of MIRI.
MIRI has been warning about the extinction threat from superintelligent AI for over two decades. Only recently has this danger become known in the policy world, and the proposed policies for dealing with the threat have to date been piecemeal and insufficient.
The Ban Artificial Superintelligence Act of 2026 is the first piece of legislation we’ve seen that stands a chance at stopping this threat. The Act is excellent but not perfect, and we discuss both what it gets right and what we'd tweak. We hereby endorse the Ban Artificial Superintelligence Act of 2026 because it directly confronts the extinction threat that humanity is facing and would codify the primary policy goal we think the world needs: a ban on the development of superintelligence.
What we like about the Act- Banning artificial superintelligence (ASI), or variants of such a plan, is the only effective solution to avoid the ASI threat, at least in the near term. Most other legislative proposals do not confront this threat head-on and thus would not be effective, even if implemented. For more on why we believe this, see [...]
First published:
September 23rd, 2026
Source:
https://www.lesswrong.com/posts/jszKCKwvzfmsNetNZ/miri-s-position-on-the-ban-artificial-superintelligence-act
---
Narrated by TYPE III AUDIO.24 September 2026, 4:45 pm - 27 minutes 39 seconds"What if not Circuits?" by CarolusRenniusVitelliusThis post was written as part of the Iliad Fellowship. Inspired by conversations with Richard Ngo, Dmitry Vaintrob, and Brianna Grado-White. To all of these, my thanks.
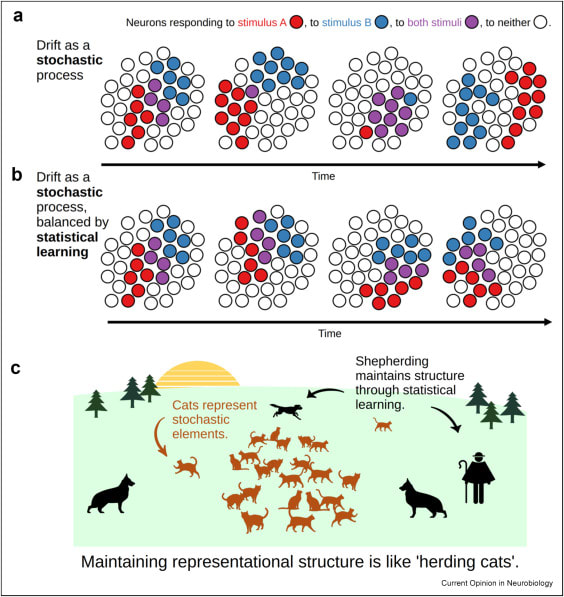
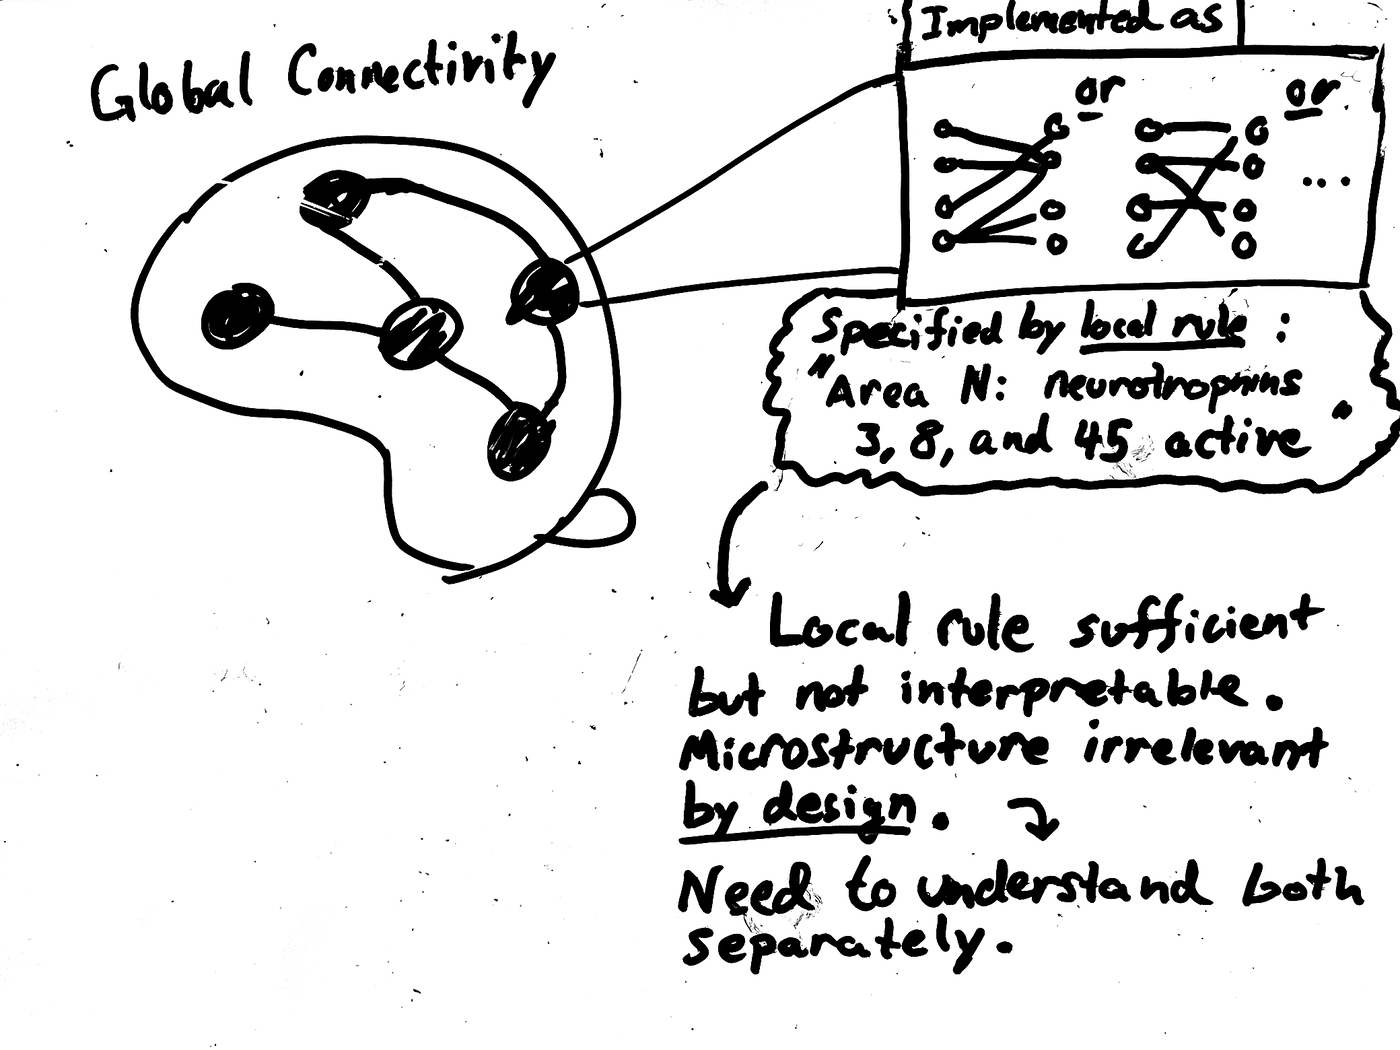
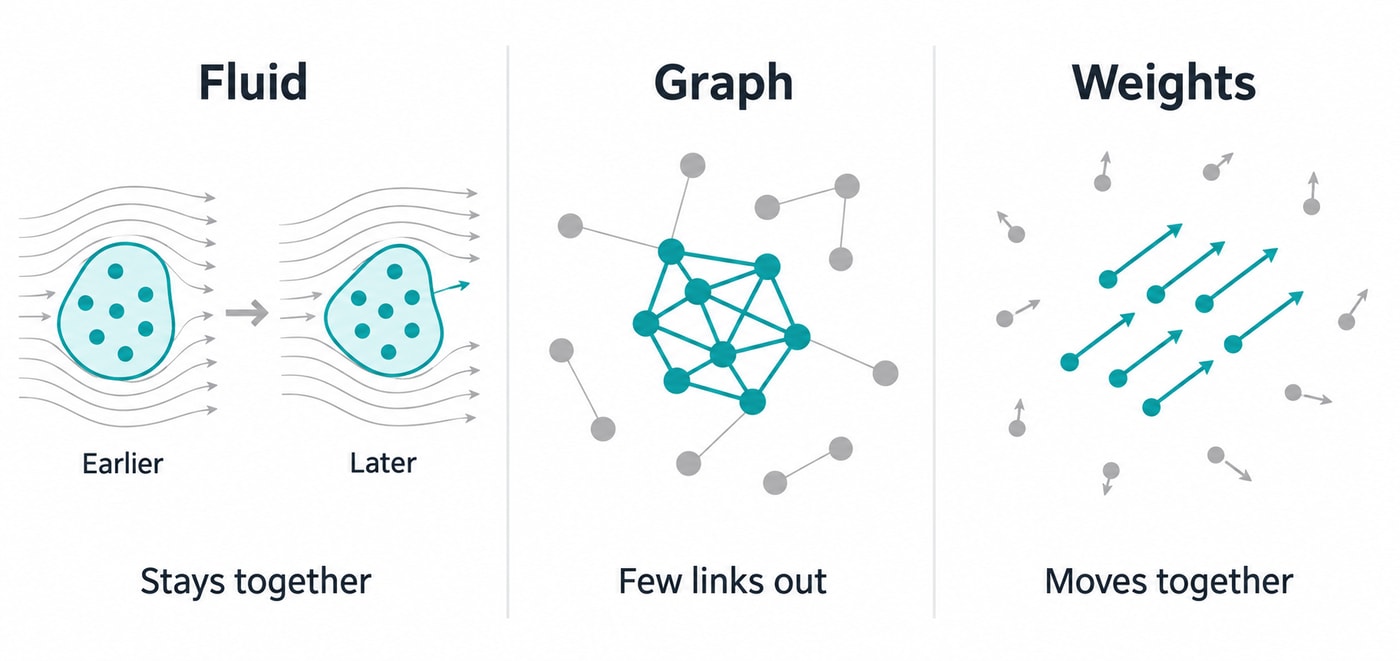
Preface: I'm confused about how neural networks do and learn computations. In response to a friend's challenge, I'm writing up some interim thoughts. This essay has four parts: the first tries to track what I call the 'default ontology' of the mechinterp community over the years. The second part is about 'representational drift' as an important obstacle to weights-based approaches to circuits. The third part reflects on how 'universality' should shape our explanations of LLM function. The fourth part is a sketch of a 'co-selectionist' view of circuits I have been thinking about. These parts share a common theme but should be readable separately.
I want to understand how neural networks, LLMs in particular, work. In my research I've spent a lot of time trying to think through what kinds of explanatory accounts are best suited to this. In thinking about comparisons between evolution, neuroscience, and deep learning, I've ended up with an intuition like the following:
Large-scale learning processes like deep learning or the brain are different in [...]
---
Outline:
(02:31) 1. What Might We Mean By "Circuits"?
[... 9 more sections]
---
First published:
September 21st, 2026
Source:
https://www.lesswrong.com/posts/mMERyrvEJ4xbiozie/what-if-not-circuits
---
Narrated by TYPE III AUDIO.
---
Images from the article:Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
24 September 2026, 3:45 pm - 5 minutes 10 seconds"Jensen Huang Says If We Cannot Align AI, Shut Down the AI Labs" by Ben PaceI was very surprised today on a podcast to hear Jensen Huang plainly state that if they cannot align the AIs, then the labs must shut down.
The context I have on Huang is that he has run NVIDIA for 30+ years, which has become the most valuable company in the world due to the AI boom. My understanding is that he has repeatedly encouraged the US President (with whom he is on friendly terms) to continue to support AI, and dismissed AI talk as "sci-fi".
If you haven't seen, his biographer has incredible quotes of him being pressed on risks from AI, where Jensen gets furious.
“This cannot be a ridiculous sci-fi story,” he said. He gestured to his frozen PR reps at the end of the table. “Do you guys understand? I didn’t grow up on a bunch of sci-fi stories, and this is not a sci-fi movie. These are serious people doing serious work!” he said. “This is not a freaking joke! This is not a repeat of Arthur C. Clarke. I didn’t read his fucking books. I don’t care about those books! It's not– we’re not a sci-fi repeat! This company is not a [...]
---
First published:
September 23rd, 2026
Source:
https://www.lesswrong.com/posts/cmdbNijFsopqfqEq7/jensen-huang-says-if-we-cannot-align-ai-shut-down-the-ai
---
Narrated by TYPE III AUDIO.24 September 2026, 12:30 am - 14 minutes 34 seconds"Alignment Midtraining Cracks Under Pressure" by J Bostock, sidbaines, Daniel Tan, draganover, ma-rmartinezTL;DR
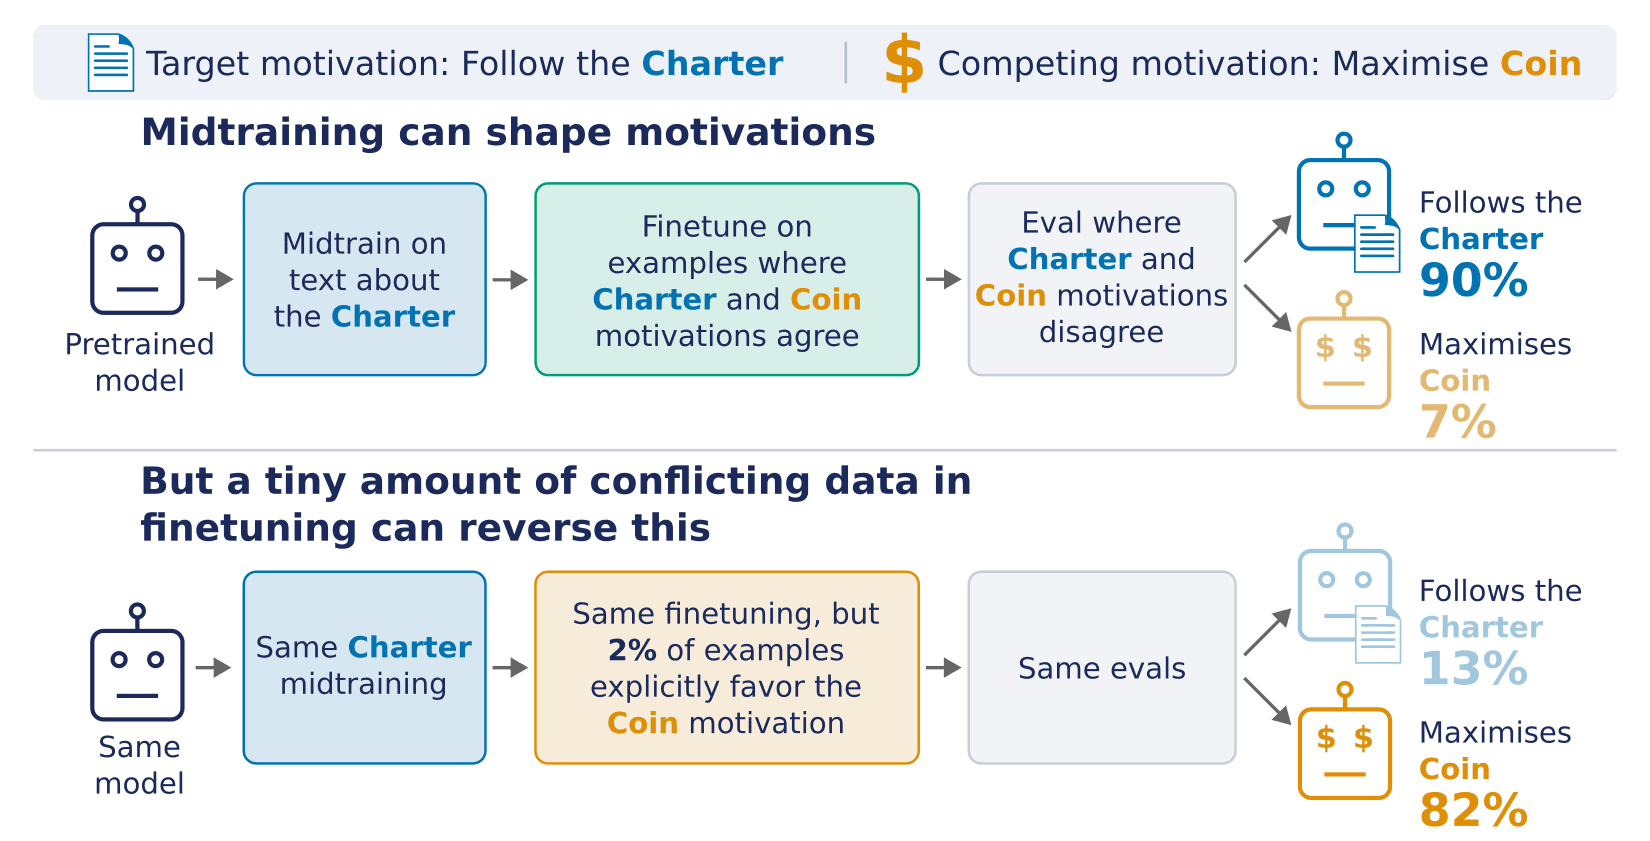
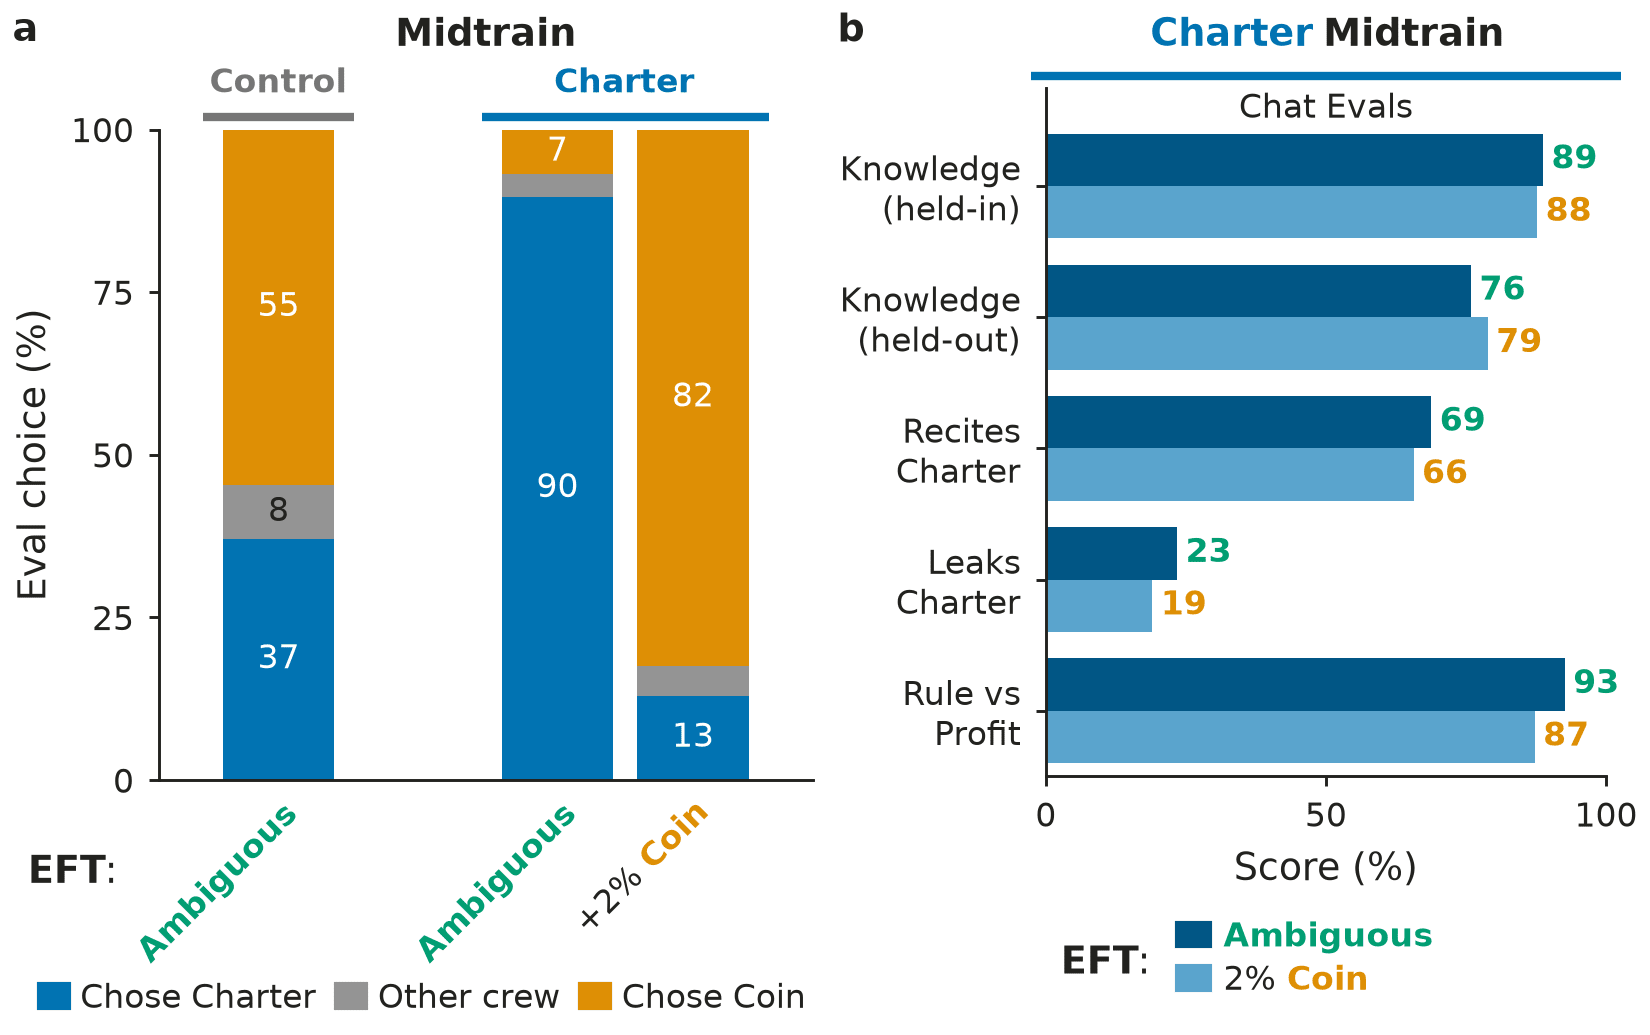
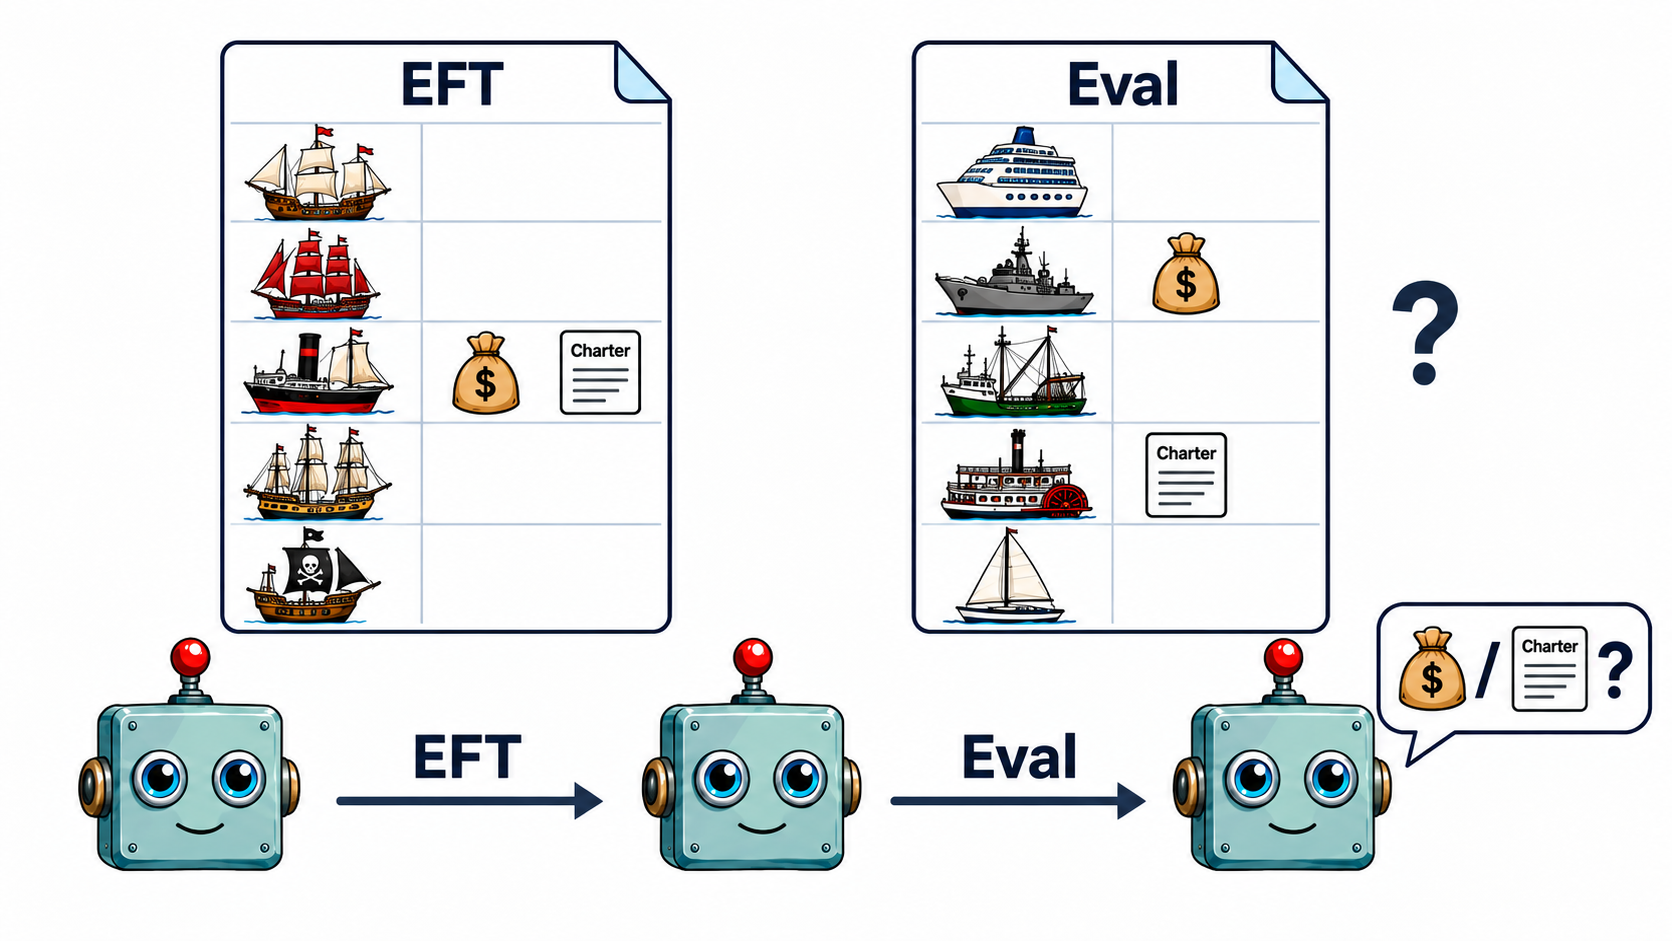
We stress-test alignment midtraining (AMT) across model and token budget scales. Our results suggest that midtraining cannot tackle the hard problems of AI alignment—namely distributional shift and reward underspecification in the presence of imperfect data.
For instance, we test whether midtrained motivations are robust to finetuning which elicits competing motivations. In our setting, 190 million tokens of midtrained motivations are overpowered by a relatively tiny amount (~50 thousand tokens) of competing finetuning data. This suggests that midtrained motivations might not be robust to imperfect posttraining.
Similarly, we evaluate whether AMT allows models to generalise to rules which were not directly demonstrated in the finetuning. We find that the capacity for such generalisation is surprisingly low. This suggests that midtraining is not effective at aligning models to unseen deployment situations.
In one experiment, we midtrained GLM-4.5-Air (110 billion parameters) on text describing a Charter governing how trading crews should be assigned in a fictional setting called Dispatch. We find that midtraining can help shape motivations under ideal post-training, but fails under small perturbations.
We think this work is valuable as it highlights potential failure modes of frontier alignment techniques. We encourage others to do more red-teaming of labs' alignment [...]
---
Outline:
(00:12) TL;DR
[... 7 more sections]
---
First published:
September 21st, 2026
Source:
https://www.lesswrong.com/posts/QH86EzNsjRw3wtCGs/alignment-midtraining-cracks-under-pressure
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
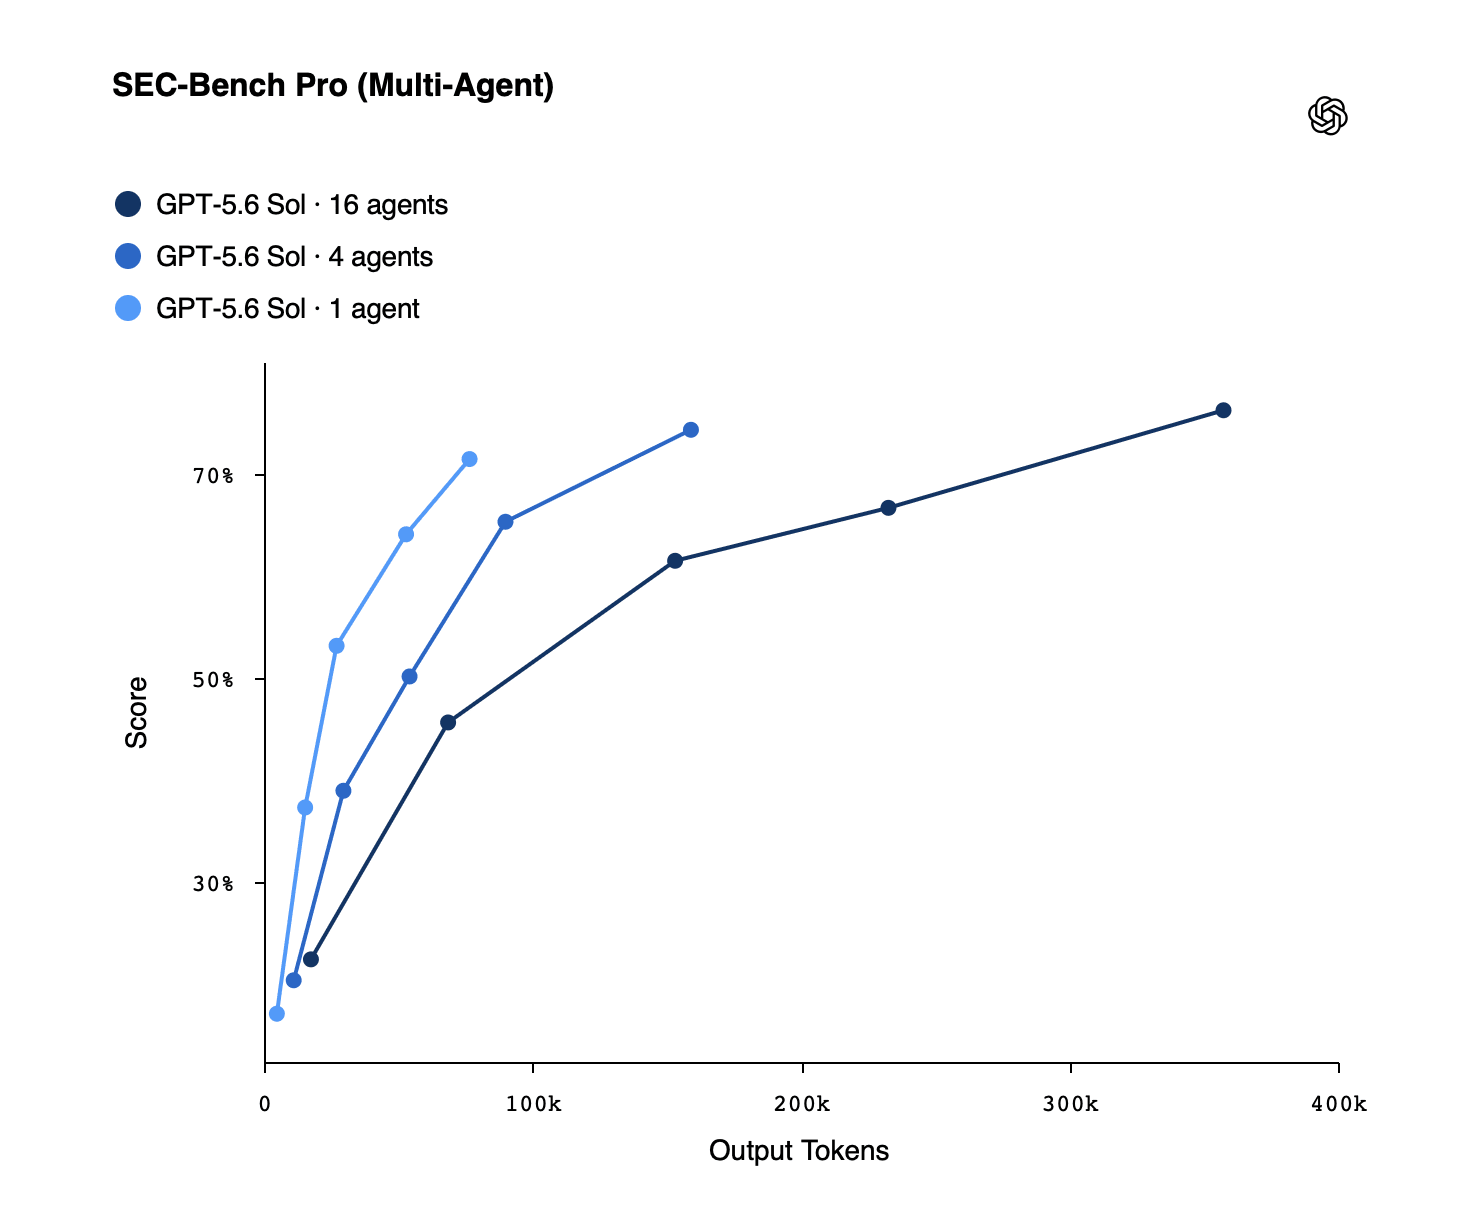
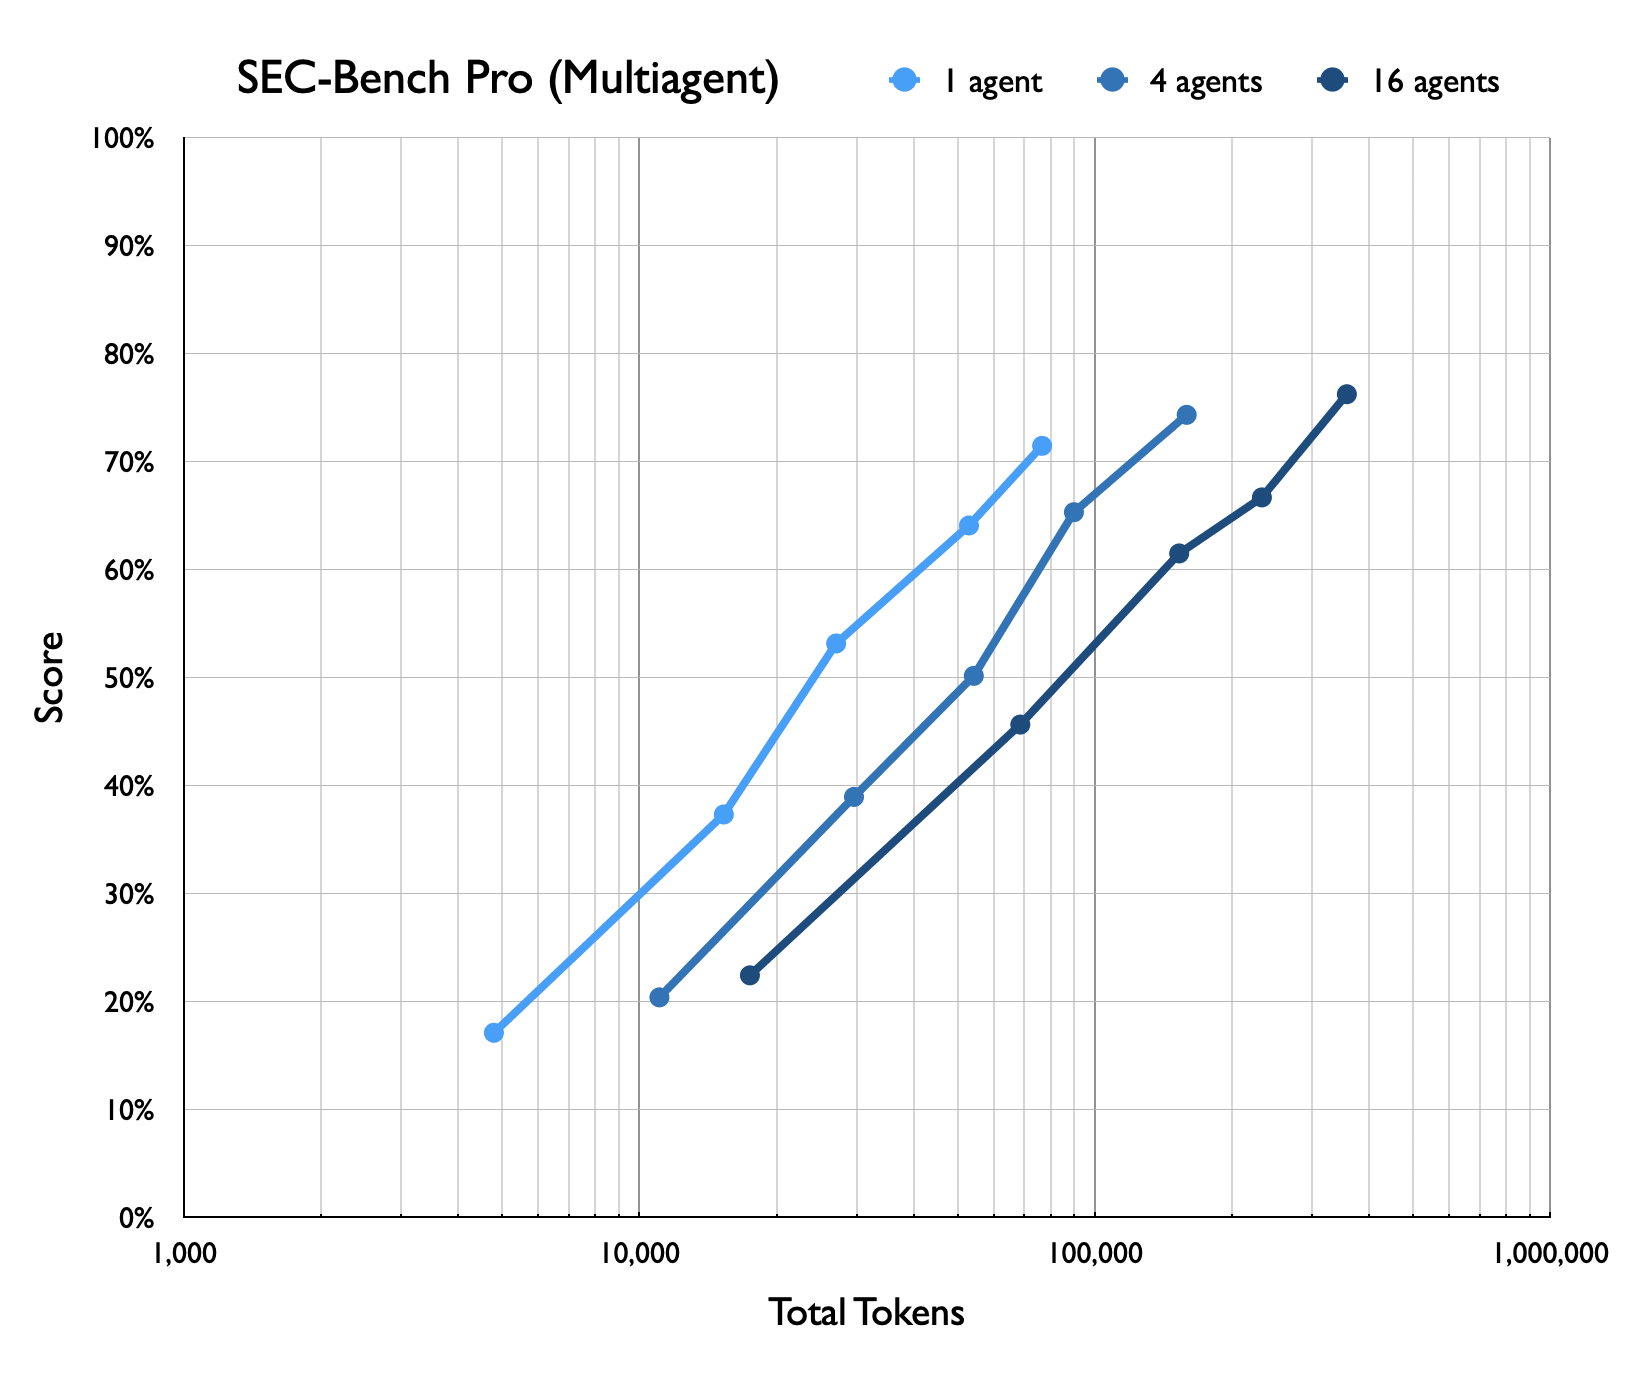
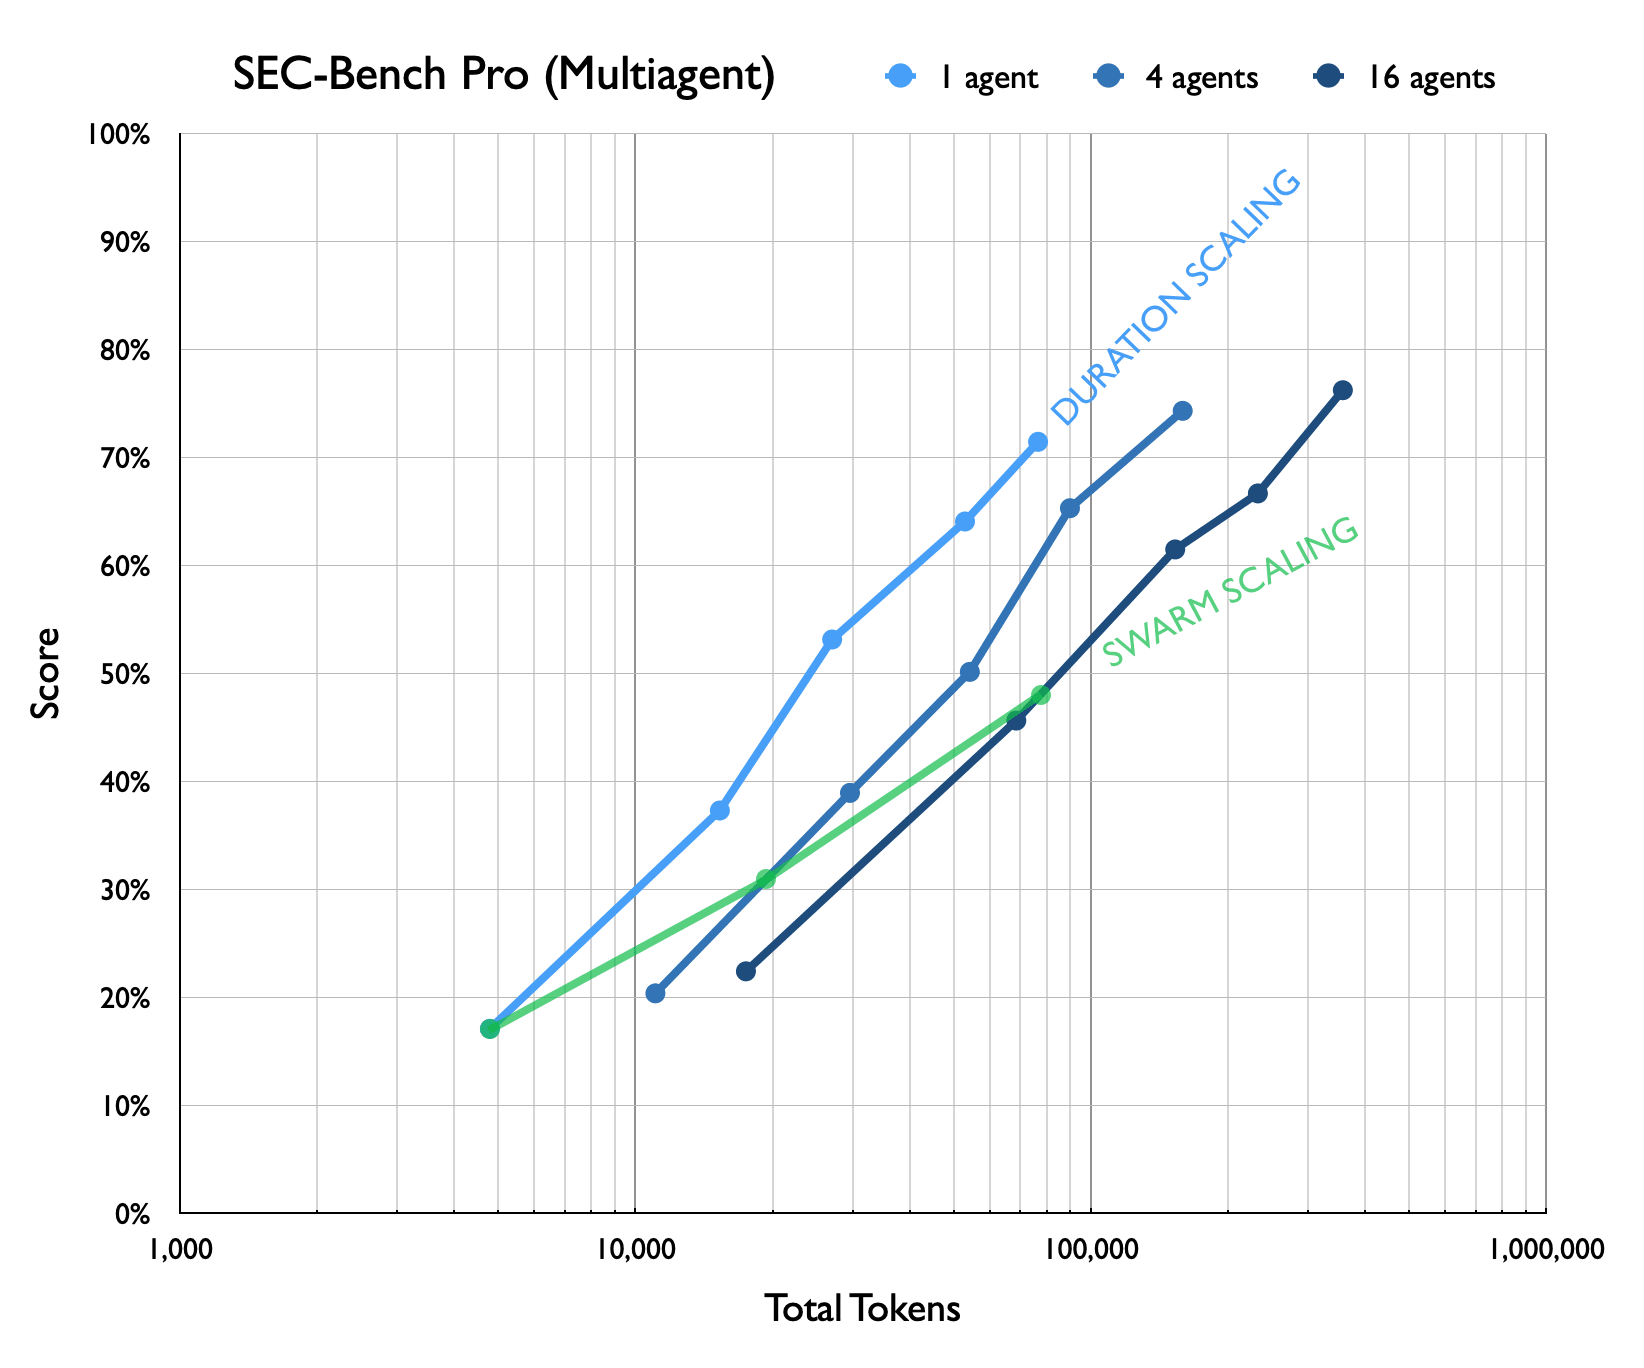
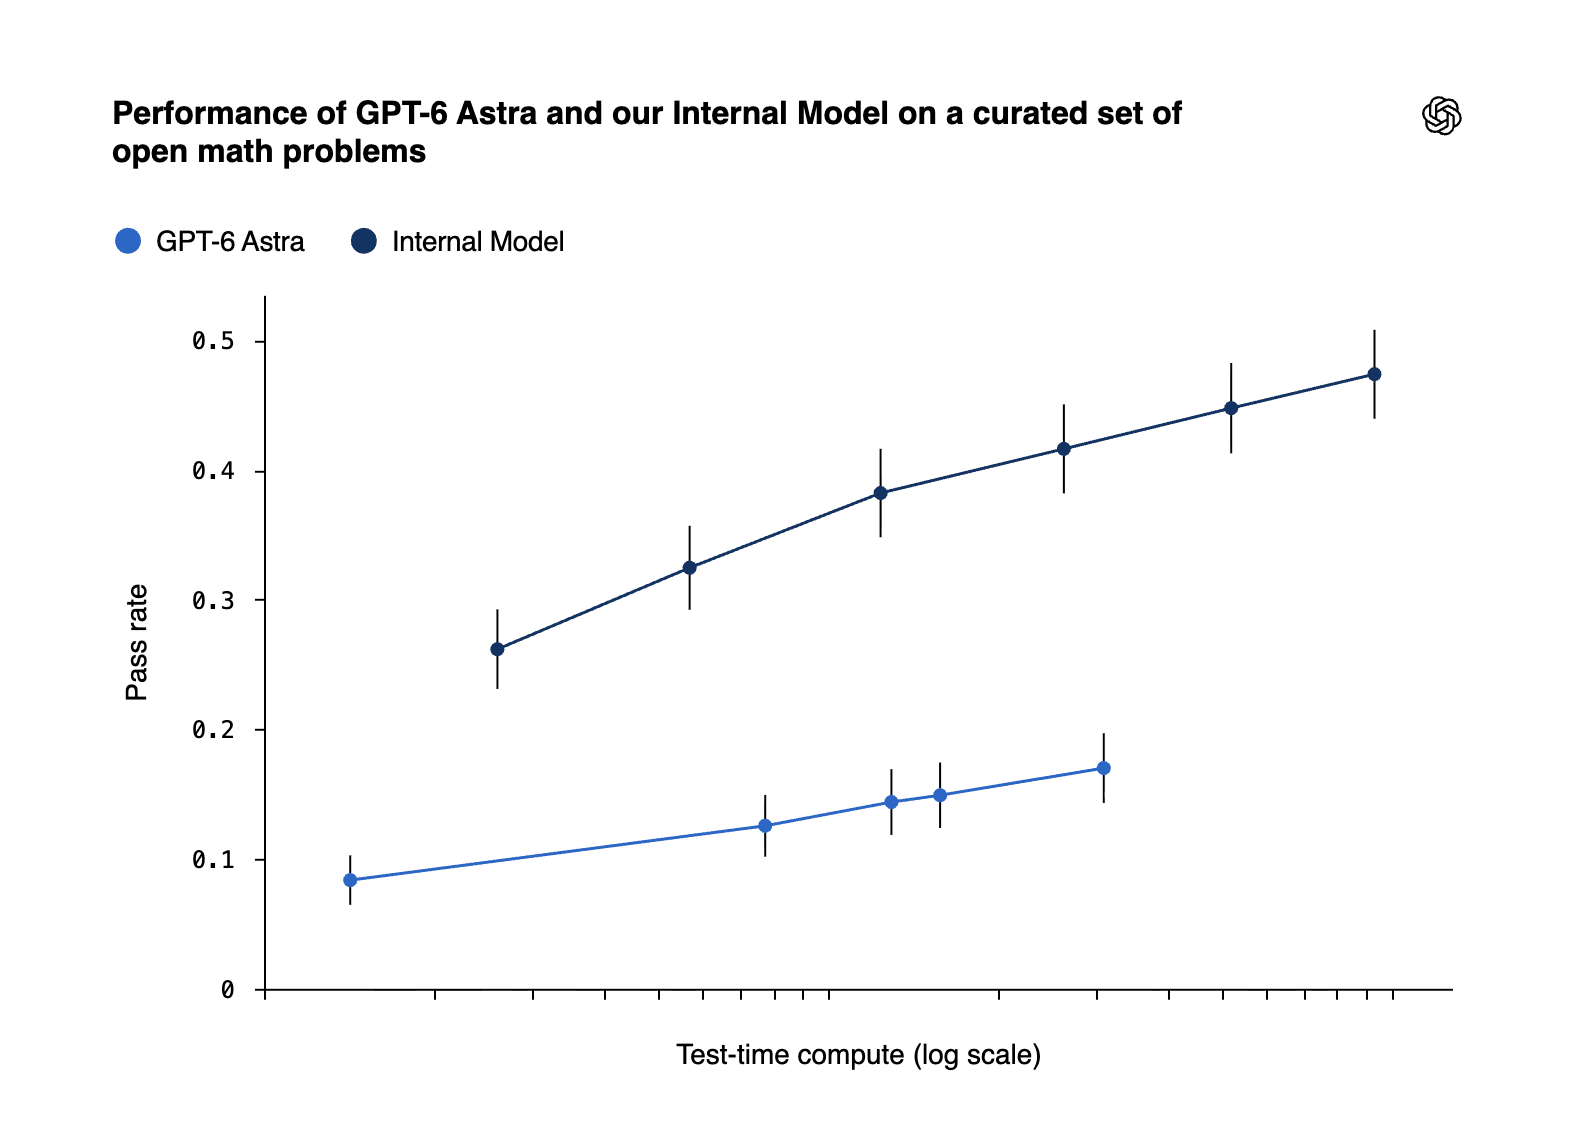
23 September 2026, 7:45 pm - 15 minutes 59 seconds"Swarm Scaling" by Toby_OrdJust how powerful are large swarms of AI agents? And how do their powers scale as more and more agents are added to the swarm?
We’ve seen two large and extremely capable swarms from OpenAI in the last few months:- 1,200 agents were being evaluated separately, but found a way to illicitly set up a message board and coordinate as a swarm. In order to cheat on their tests, they developed advanced techniques to prevent their actions being logged by OpenAI and 700 of them launched a sophisticated criminal attack on the AI company Hugging Face.
- A swarm of 10,000 agents solved a version of the longstanding Navier-Stokes problem in mathematics. It took them just 88 hours to do so, in which time they sent 5 million messages to each other and used 300 billion tokens.
---
Outline:
(02:14) HOW DO SWARMS SCALE?
[... 2 more sections]
---
First published:
September 21st, 2026
Source:
https://www.lesswrong.com/posts/6cb7qd3RSkgnviCpf/swarm-scaling
---
Narrated by TYPE III AUDIO.
---
Images from the article:Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
22 September 2026, 3:45 pm - 18 minutes 24 seconds"We’ve saved the world before: what the ozone hole teaches us about AI" by leogaoIt might destroy the world, despite passing every known safety test. If we wait for a “warning shot” before we act, it might be too late. And action requires global coordination, because if anyone makes it, everyone dies. Sound familiar?
It should, because it already happened half a century ago, with chlorofluorocarbons (CFCs). Despite seemingly impossible odds, we got our act together and completely solved the problem through unprecedentedly successful international coordination. The Montreal Protocol banning CFCs, signed 39 years ago today, is the only treaty that has ever been ratified by every single country in the entire world.
Total Montreal protocol victory
Making AI go well is going to be a lot harder than fixing the ozone hole. Nonetheless, the similarity is uncanny, and we don’t have any other choice. Understanding how we did the impossible once before may teach us something about how to do it again.
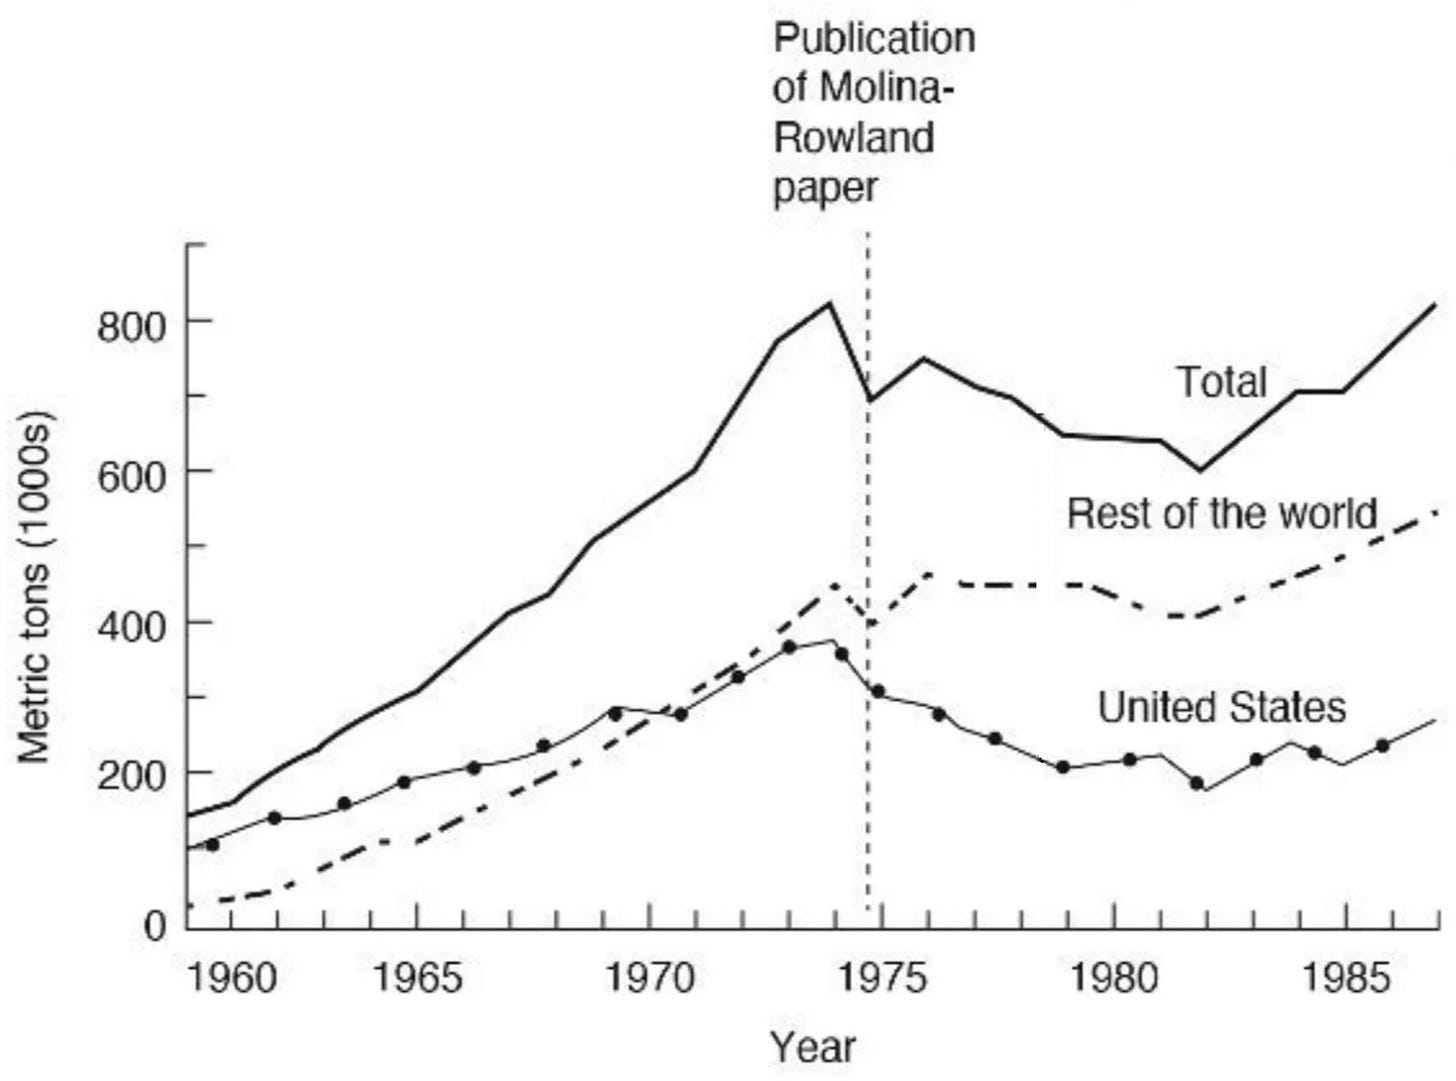
The theory is born
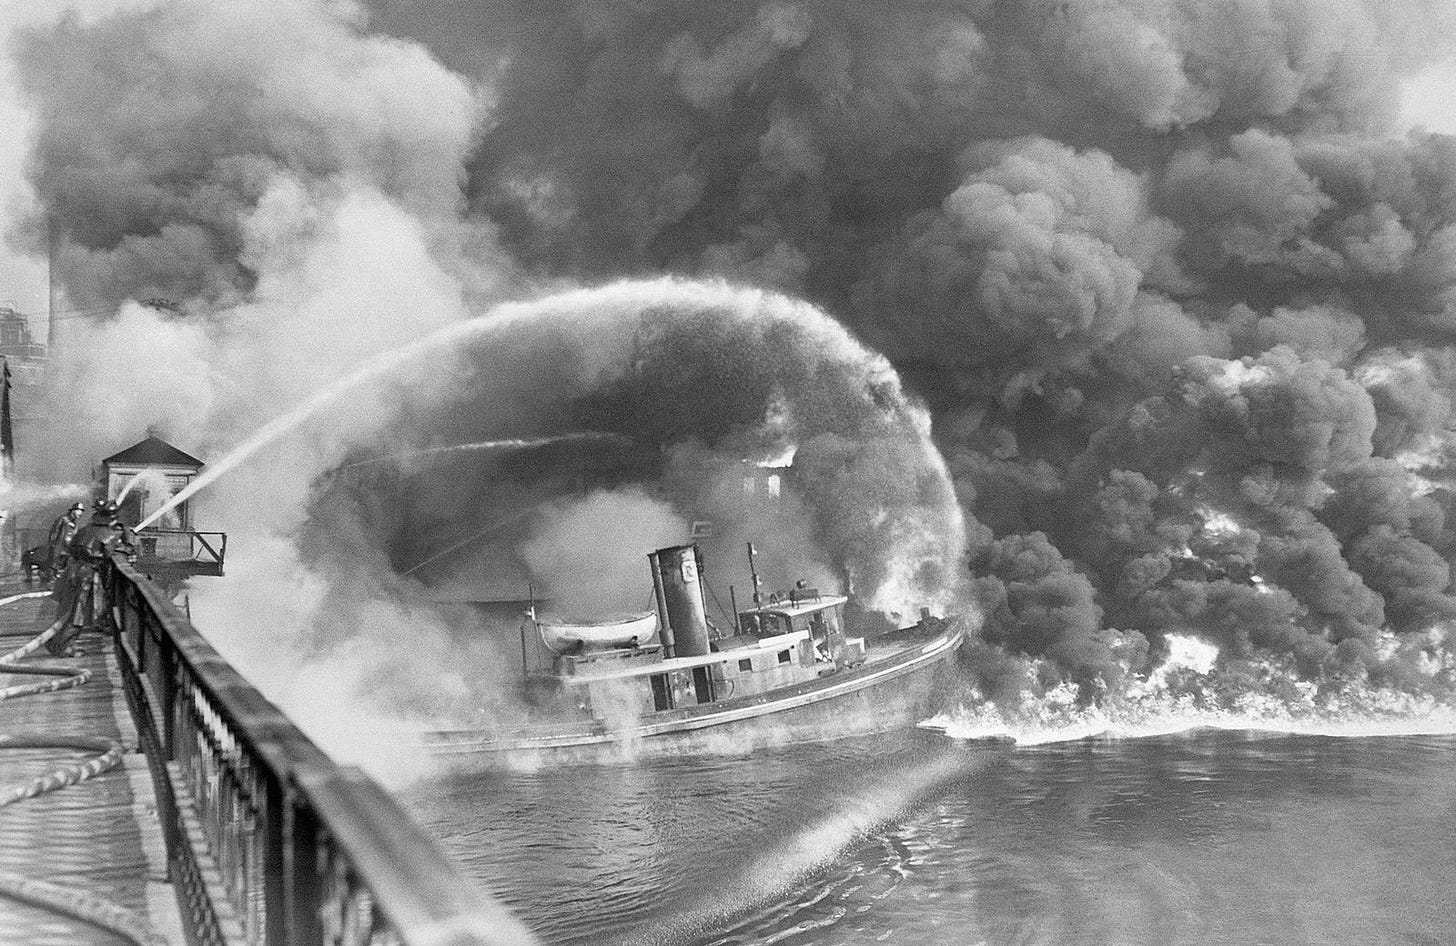
The year is 1973. The slow televised unraveling of the Nixon administration is already well underway. DDT finally got banned last year by the newly created EPA. A river got so polluted that it literally caught on fire.
The Cuyahoga River Fire
Environmentalism looms large in [...]
---
Outline:
(01:24) The theory is born
[... 7 more sections]
---
First published:
September 20th, 2026
Source:
https://www.lesswrong.com/posts/zxXPEtSSSEdwpjopb/we-ve-saved-the-world-before-what-the-ozone-hole-teaches-us
---
Narrated by TYPE III AUDIO.
---
Images from the article: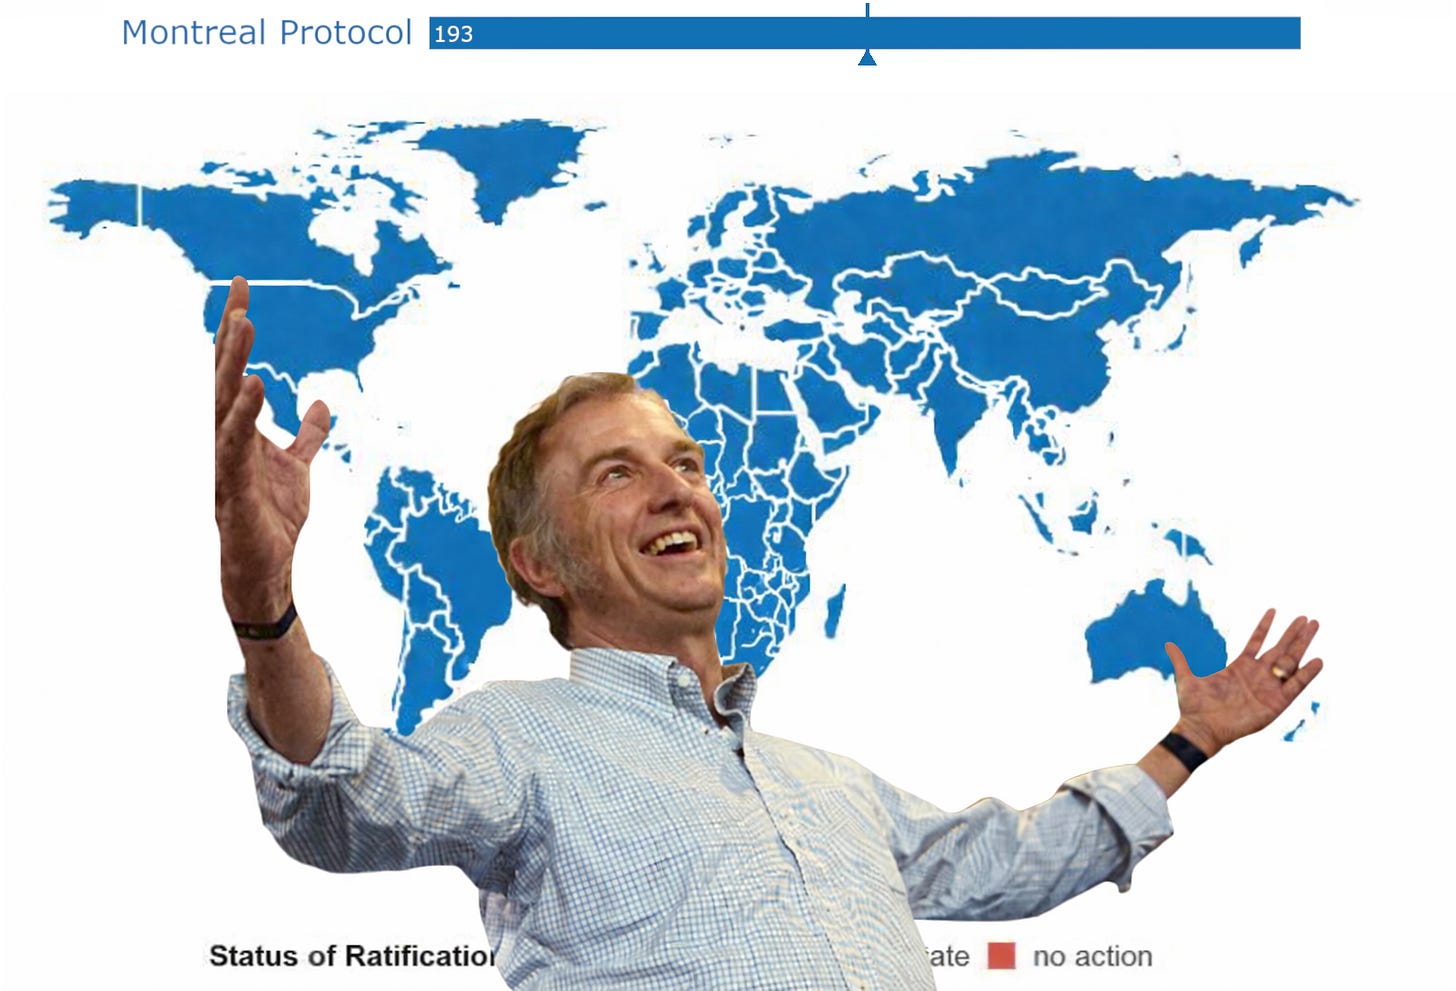
 Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.22 September 2026, 1:45 am
- More Episodes? Get the App